


SQL on your lakehouse →
Query every table with standard SQL.
Trino coreApache Iceberg coreLakekeeper core
Why: Trino reads Iceberg tables in place and scales out.


Iceberg tables, SQL, pipelines, notebooks, streams and dashboards behind one sign-in, one interface and one API, inside your own Kubernetes.
Iceberg RESTTrinoSpark ConnectKafka (KRaft)Airflow 3OIDCOpenFGARust control plane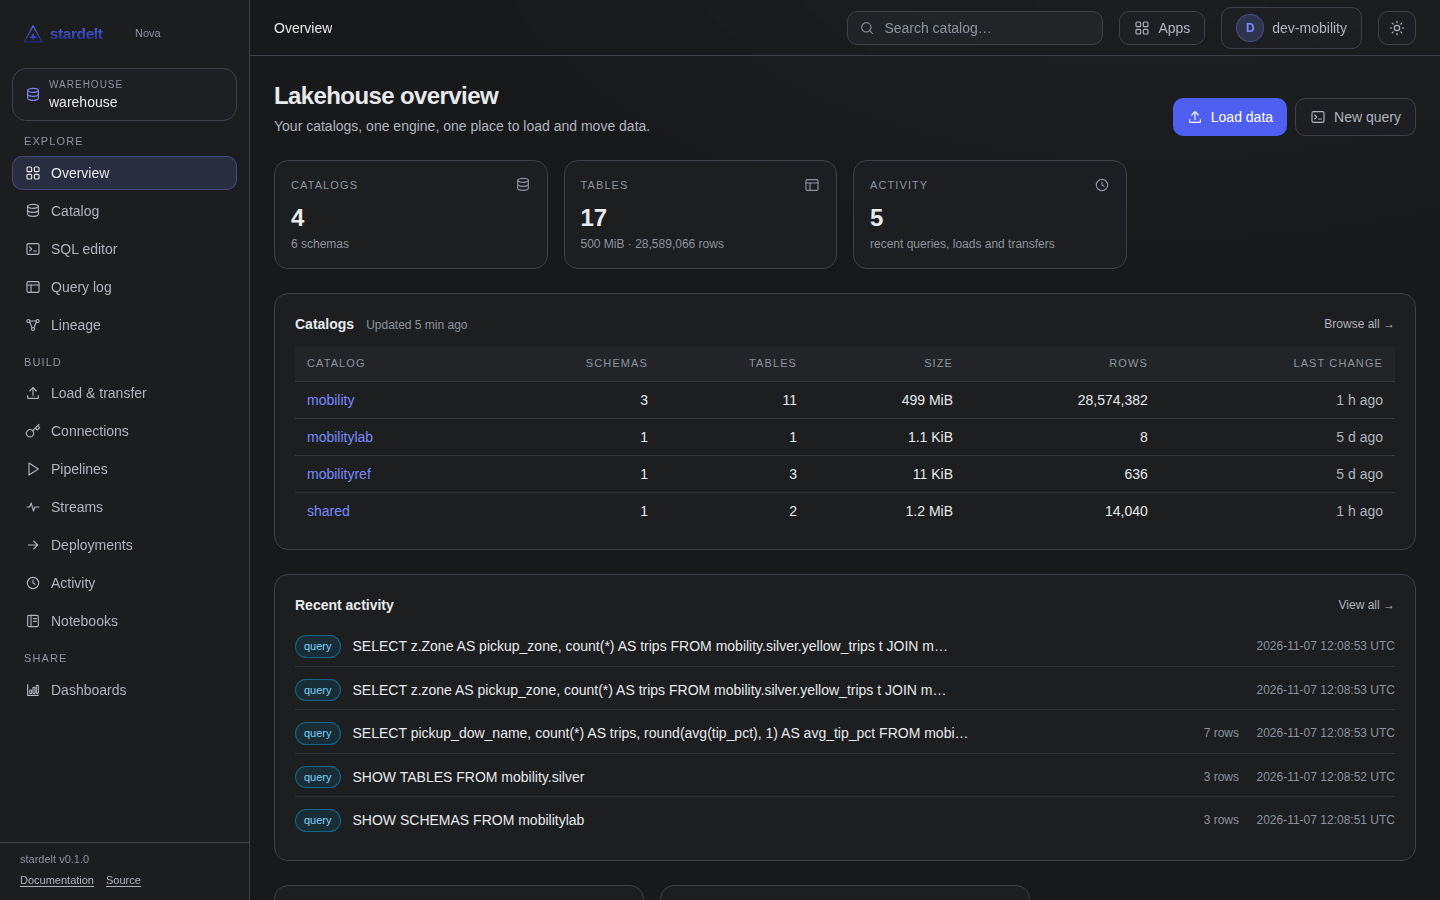
Taxi trips arrive as a file at 7:00. By 9:00 the team has a modelled table, a daily schedule, lineage and a dashboard, without leaving one interface.

Every engine reads and writes the same Iceberg tables through one catalog. stardelt Nova brings them together.

Logos are trademarks of their respective owners; their use does not imply endorsement.
core always installedstarter for small installs, replaceabledefault full profile, switchable per pillaropt-in off until you enable itplug you bring your own
Query every table with standard SQL.
Why: Trino reads Iceberg tables in place and scales out.
Tables live on object storage you choose.
Why: Enterprises already run object storage, and stardelt uses it.
Files and sources become tables.
Why: Loading is a feature of the platform, not a separate tool to buy and operate.
Bronze to silver to gold, on a schedule.
Why: Pipelines are declared in Git and moved between stages.
Python and Spark jobs without a Spark cluster per person.
Why: A thin client talks to a shared Spark server: no spark-submit, no driver on your laptop.
Explore next to the data, then publish and schedule.
Why: Notebooks run inside the platform with the person's own permissions, and published ones run as pipeline steps.
Events in, tables out.
Why: The streaming pillar is opt-in and off until you enable it.
Charts on governed tables.
Why: Dashboards query through Trino with the viewer's permissions, so there is no copy of the data.
One sign-in, permissions by team.
Why: You keep the identity provider you already have.
No passwords in files.
Why: Secrets come from the store you already run, through External Secrets.
Three promises that hold from the first install.
Your cluster, your sign-in, your storage, your law.
Apache 2.0, open formats, and a real way out.
No legacy inside: every part is current-generation open source.
What you click in Nova, you can script, schedule, review in Git, or hand to an AI assistant, always as yourself and with your permissions.
stardelt login
stardelt sql "select * from mobility.silver.yellow_trips limit 5"
stardelt run stardelt mobility-medallion --wait
from stardelt import runs
run, tasks = runs.start(nova, "stardelt", "mobility-medallion", wait=True)
apiVersion: stardelt.io/v1alpha1
kind: Pipeline
metadata: { name: mobility-medallion }
spec:
  ownerGroup: mobility-analytics
  runAs: pipeline-mobility-analytics
  schedule: { cron: "0 3 * * *", timezone: Europe/Berlin }
  tasks:
    - { name: silver_schema, kind: sql, sql: "CREATE SCHEMA IF NOT EXISTS mobility.silver" }
    - { name: silver_init, kind: sql, dependsOn: [silver_schema], sql: "CREATE OR REPLACE TABLE mobility.silver.yellow_trips AS …" }
stardelt mcp config      # how to register the server in your assistant
stardelt mcp serve       # read-only tools unless you allow more
Read operations only by default. Every call is checked against your groups, exactly as in the interface. API, Python, CLI and MCP →.
git clone https://github.com/stardelt/stardelt-platform
cd stardelt-platform
helm dependency build chart

helm upgrade --install stardelt chart \
  --namespace stardelt --create-namespace \
  -f chart/values-slim.yaml --wait --timeout 15m
stardelt is pre-alpha and grows in milestones. See what works today and what comes next →